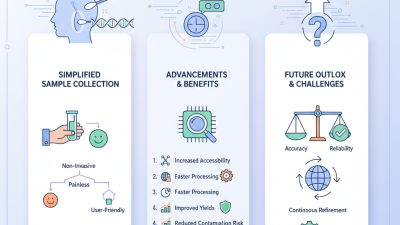
Choosing among DNA analysis workflows is not simply a matter of selecting the newest sequencer. It is a practical design decision. The best workflow connects the biological question, sample type, laboratory capacity, and reporting requirements. A forensic swab, tumor biopsy, and environmental water sample behave differently. Each requires suitable preparation, controls, and interpretation. Small details matter. A frozen tube may thaw during transport. Inhibitors can hide a genuine signal. A crowded amplification plate can create confusing patterns.
As Nobel laureate and molecular biologist Sydney Brenner observed, “Progress in science depends on new techniques, new discoveries and new ideas, probably in that order.” His observation remains relevant to modern DNA analysis workflows. New platforms can improve speed, sensitivity, or scale. They do not automatically improve scientific judgment. Experienced teams still examine extraction quality, contamination risks, sequencing depth, and validation evidence. They also ask whether a result can be reproduced by another analyst using the same records and controls.
This guide examines how to compare workflows with discipline rather than enthusiasm. It considers laboratory experience, instrument compatibility, bioinformatics requirements, quality assurance, and total operating cost. It also addresses turnaround time and result interpretation. Faster is not always better. Cheaper is not always efficient. Some choices may look reasonable but fail under real sample pressure. That is worth admitting. No workflow is perfect for every purpose. A strong decision therefore begins with clearly defined acceptance criteria, documented limitations, and independent review. The goal is not merely to generate data. The goal is to produce reliable, interpretable evidence that supports responsible scientific decisions.
Defining goals is the most important step in DNA analysis. Start with purpose. Are you identifying variants, comparing samples, or measuring genetic diversity? Each question requires different methods, controls, and reporting standards. Write the expected outcome in one sentence. Keep it measurable. For example, specify the minimum detection level, acceptable error rate, and reporting format before selecting equipment or software.
The sample also shapes the workflow. Record its source, condition, quantity, and likely contaminants. A small, degraded sample may need extra preparation and stricter quality checks. Decide how many samples require processing, how quickly results are needed, and who will review them. In my laboratory experience, teams often focus on speed first. That choice can create repeat testing, hidden costs, and weaker confidence in the final data.
Reliable planning includes negative controls, reference materials, replicate testing, and documented approval steps. Confirm that the method fits current scientific guidance and local privacy requirements. Protect personal data throughout storage, analysis, and reporting. Automated analysis can reduce routine errors, but it should not replace qualified review. I have seen promising workflows fail because the success criteria were vague. That is worth reconsidering. Leave room for pilot testing, unexpected sample behavior, and changes after validation. A practical workflow should be accurate, traceable, and realistic for the people using it every day.
Choosing a DNA workflow begins with the sample, not the instrument. Blood, saliva, tissue, and environmental swabs release DNA differently. A clean blood sample may need simple cell lysis and silica-based purification. Soil or food samples often contain inhibitors that require extra washing. These compounds can disrupt amplification, even when the DNA tube looks clear. In routine laboratory work, measuring concentration alone is not enough. Purity ratios, fragment size, and repeatability also matter.
Silica columns are familiar, affordable, and easy to standardize. They work well for many small batches, but overloaded membranes can reduce recovery. Magnetic-bead methods handle automation and variable volumes more comfortably. They can also improve consistency between operators. However, bead-based protocols may lose very short fragments if washing or elution is poorly controlled. Organic extraction can produce high-quality DNA, yet it usually demands more handling and stricter safety procedures. No method wins every time.
Preparation after extraction deserves equal attention. Gentle mixing helps protect long DNA fragments, while excessive vortexing may shear them. Residual ethanol from washing can inhibit downstream reactions. A short drying step helps, but over-drying can make DNA difficult to dissolve. Low-input samples may benefit from concentrated elution, although concentration can carry inhibitors forward. I would test a small pilot set before changing an established workflow. This costs time. It can prevent a larger failure later. The best choice is the method that matches sample chemistry, required DNA quality, throughput, and the team’s actual technical control.
Choosing a DNA analysis workflow starts with the biological question, not the available instrument. Need rare variant discovery? Sequencing offers broader coverage across coding and non-coding regions. For a defined set of common variants, genotyping can be faster and more economical across large cohorts. UK Biobank’s resource documentation describes genetic data from roughly 500,000 participants, demonstrating the scale genotyping can support. However, arrays may miss novel variants, rare alleles, and structural changes. That limitation matters.
Start with the question. NHGRI cost-tracking data show that whole-genome sequencing costs fell from about $100 million in 2001 to near $1,000 per genome in recent years. The sample price is not the full budget. DNA extraction, quality control, coverage, storage, analysis, and variant interpretation can change the decision. I have seen projects choose sequencing for its flexibility, then struggle with low-quality DNA and unclear findings. That shortcut fails. For clinical or research decisions, define minimum coverage, acceptable missingness, validation methods, and reporting standards before purchasing tests. Professional frameworks from ACMG and ClinGen also stress evidence-based variant interpretation, rather than treating every detected change as meaningful. Genotyping suits stable, well-characterized targets. Sequencing suits discovery and uncertain biology. Neither is automatically superior; phenotype quality and follow-up capacity often decide the workflow.
| Workflow | Technology Class | Primary Biological Question | Typical Data Output | Key Strengths | Main Limitations | Best-Fit Use Cases |
|---|---|---|---|---|---|---|
| SNP Genotyping | Genotyping | Which predefined single-nucleotide variants or short insertion/deletion markers are present? | Usually hundreds of thousands to several million selected markers per sample; results are commonly reported as genotype calls and quality scores. | High sample throughput, relatively low cost per sample, straightforward analysis, and strong reproducibility for established markers. | Detects only variants represented by the assay or reliable imputation reference data; limited ability to identify novel variants, rare alleles, and structural changes. | Population studies, ancestry analysis, genetic risk research, linkage studies, sample identification, and large cohort screening. |
| Targeted DNA Sequencing | Sequencing | What sequence changes exist within a defined set of genes, exons, hotspots, or genomic regions? | Sequence reads from selected regions; coverage is often substantially higher than in broad sequencing workflows, with depth selected according to the variant-detection objective. | Efficient use of sequencing capacity, high analytical depth, focused interpretation, and suitability for known disease or research targets. | Findings are restricted to the captured or amplified regions; assay design can miss variants near target boundaries, repetitive regions, or poorly amplified loci. | Focused variant panels, inherited disease research, pharmacogenomic targets, cancer-associated regions, and validation of specific loci. |
| Whole-Exome Sequencing | Sequencing | Which variants occur in protein-coding regions across most annotated genes? | Approximately 1–2% of the human genome is targeted, representing roughly 20,000 protein-coding genes; output consists of coding-region reads and variant calls. | Broader discovery than targeted panels while requiring less data and analysis than whole-genome sequencing; useful for coding single-nucleotide and small insertion/deletion variants. | Incomplete or uneven coverage of exons, limited detection of regulatory and intergenic variants, and reduced sensitivity for some structural variants and repeat expansions. | Rare-disease gene discovery, coding-variant research, family-based studies, and projects where the main hypothesis concerns protein-altering variants. |
| Whole-Genome Sequencing | Sequencing | What genetic variation is present across coding, regulatory, intergenic, mitochondrial, and other genomic regions? | Sequence data covering the nuclear genome and usually mitochondrial DNA; short-read projects commonly use approximately 30× average coverage for germline analysis, although requirements vary. | Broadest single-assay view of the genome, more uniform representation than capture-based assays, and improved ability to study noncoding and diverse variant classes. | Higher data-generation, storage, and interpretation demands; repetitive regions, complex rearrangements, and some repeat expansions may still require specialized methods. | Comprehensive germline research, population genomics, structural-variant studies, pathogen or reference-genome projects, and cases unresolved by narrower assays. |
| Low-Pass Whole-Genome Sequencing with Imputation | Sequencing | Can low-depth genome-wide reads provide broad genotype information when combined with a suitable reference panel? | Genome-wide reads generated at low average depth, followed by statistical genotype imputation; accuracy depends on coverage, ancestry match, marker frequency, and reference-panel quality. | Provides more flexible marker discovery than fixed genotyping assays and can scale efficiently for large cohorts. | Imputed genotypes are probabilistic, rare or population-specific variants may be less accurate, and direct confirmation may be needed for important findings. | Large population cohorts, genome-wide association studies, genetic diversity studies, and projects requiring a broad but cost-conscious variant set. |
| Long-Read Genome Sequencing | Sequencing | How are long, complex, repetitive, or structurally rearranged genomic regions organized? | Long sequence reads that can span repeated elements, breakpoints, phased haplotypes, and larger insertions or deletions; accuracy and read length depend on the laboratory method and analysis pipeline. | Stronger resolution of structural variants, repeat-rich regions, haplotypes, and difficult-to-map loci than many short-read approaches. | Often requires higher input-DNA quality, specialized analysis, and greater cost or lower throughput for some study designs; small-variant accuracy may require method-specific quality control. | Genome assembly, structural-variant discovery, repeat-expansion research, haplotype phasing, and unresolved cases involving complex genomic regions. |
| Mitochondrial DNA Sequencing | Sequencing | Which variants and heteroplasmy levels occur in the mitochondrial genome? | Sequence reads from the approximately 16.6 kb mitochondrial genome, with depth selected to support detection of low-level heteroplasmy and to distinguish mitochondrial reads from nuclear mitochondrial segments. | Focused assessment of mitochondrial variation and potentially high read depth from suitable DNA preparations. | Nuclear mitochondrial DNA segments can complicate alignment; heteroplasmy estimates are affected by sample type, contamination, depth, and technical artifacts. | Mitochondrial disease research, maternal-lineage studies, heteroplasmy analysis, and investigations of mitochondrial population variation. |
| Bisulfite-Based DNA Methylation Analysis | Sequencing | Which cytosine methylation patterns are present at selected or genome-wide CpG sites? | Converted DNA sequence reads used to estimate methylated and unmethylated cytosines; results are generally reported as methylation percentages by site or region. | Measures an epigenetic DNA modification rather than only DNA sequence, with resolution ranging from selected regions to broad genomic coverage. | DNA conversion can damage or bias templates; interpretation is tissue- and cell-composition-dependent, and standard bisulfite methods do not distinguish all cytosine modifications. | Epigenetic regulation, development, environmental-response studies, disease-associated methylation, and tissue-specific biomarker research. |
| Confirmatory Sanger-Style Sequencing | Sequencing | Is a known sequence variant present in a specific PCR-amplified region? | High-quality sequence traces across a relatively short targeted region; useful for confirming many single-nucleotide and small insertion/deletion findings. | Simple interpretation for a limited number of loci, useful orthogonal confirmation, and effective for testing defined variants in selected samples. | Low multiplexing, limited sensitivity for low-frequency mixtures, and poor suitability for broad discovery or large cohorts. | Follow-up confirmation, family segregation testing, clone verification, and focused analysis of a small number of genomic regions. |
A reliable DNA workflow starts with accuracy, not advertising claims. Check performance using reference samples, negative controls, and repeated measurements. Examine sensitivity, specificity, coverage depth, and the rate of uncertain results. A workflow that produces more data is not always more accurate. Small errors can change interpretation, especially near detection limits.
Speed can mislead. Measure the complete turnaround time, including preparation, instrument queues, analysis, and reporting. A rapid run may create delays when batching is required.
Cost should include reagents, labor, maintenance, storage, software, and possible reruns. A cheaper test can become expensive after repeated failures. Ask for realistic estimates from your own sample volume.
Data quality matters. Confirm that files include clear sample identifiers, quality scores, processing records, and version-controlled analysis steps. Strong documentation supports review and makes unexpected findings easier to investigate.
In practice, laboratories often balance precision with budget and staffing. That balance is imperfect. A workflow may perform well with clean samples but struggle with degraded material.
Test representative samples before committing. Review failed runs, not only successful ones. This uncomfortable step often reveals the most useful information.
A reliable DNA workflow begins with the biological question, not the software list. Variant discovery, microbial identification, and population analysis require different processing decisions. In practical projects, I have learned that simple tools can outperform complex pipelines when inputs are well documented. Record sample source, extraction method, read length, and sequencing coverage. Keep the raw data.
When comparing bioinformatics tools, inspect their algorithms, update history, documentation, and computing requirements. A tool should handle your file formats without repeated manual conversion. Test it with reference datasets containing known results. Check whether its output explains quality scores, filtering thresholds, and failed reads. Small errors matter. They can change downstream conclusions.
Validation should include technical replicates, negative controls, and independent confirmation when possible. Compare results across more than one analytical method, but investigate differences instead of choosing the most convenient answer. Review mapping quality, duplicate reads, contamination signals, and uneven coverage at difficult regions. An unexpected result may reflect biology, yet it may also indicate poor sample quality or an unsuitable reference. I once treated a low-frequency variant as meaningful before checking coverage around the site. That decision needed more skepticism.
Reliable reporting states what was detected, what remains uncertain, and which limitations could affect interpretation. Also protect sensitive genetic data through controlled access, clear retention rules, and documented consent requirements.